FlowSE-RAM: Transcript-Supervised Post-Training of Generative Speech Enhancement on Real Recordings via Reinforce Adjoint Matching
Listening examples comparing the method with several baseline speech enhancement systems.
MERL Researchers: Julius Richter, Christoph Boeddeker, Yoshiki Masuyama, Gordon Wichern, Jonathan Le Roux,
with Dominik Klement (MERL intern) and Kohei Saijo (Mitsubishi Electric Corporation).
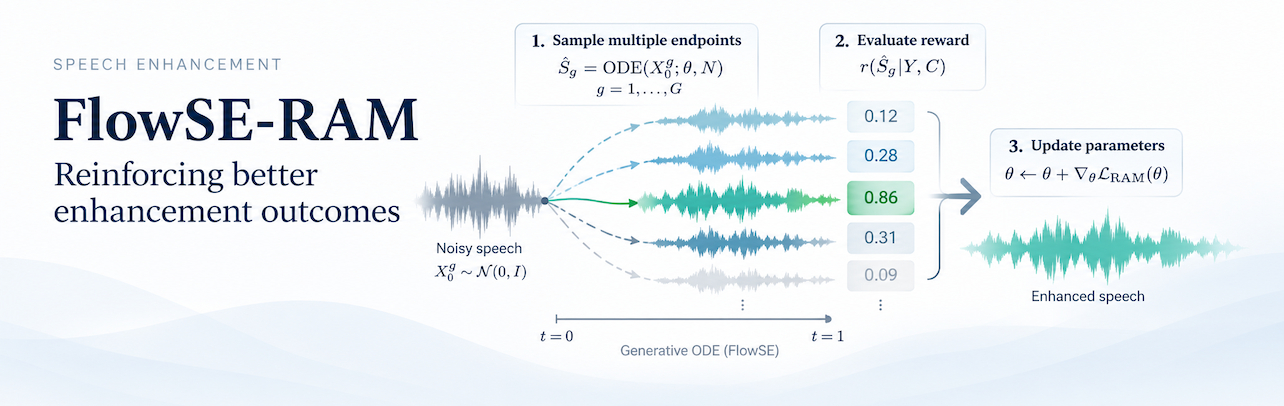
FlowSE-RAM post-trains FlowSE on real noisy recordings using only transcripts and no paired clean speech, reducing recognition errors without lowering the reported quality scores. Compare the noisy input and the four enhancement methods below, listening for noise reduction and preservation of the spoken words.
Audio examples
Representative audio examples from the CHiME-4 real test set comparing noisy speech with FlowSE and FlowSE-RAM, including other post-training baselines. The examples illustrate how the different methods affect both speech quality and recognition accuracy under real-world noise conditions.