Speech & Audio
Audio source separation, recognition, and understanding.
Our current research focuses on application of machine learning to estimation and inference problems in speech and audio processing. Topics include end-to-end speech recognition and enhancement, acoustic modeling and analysis, statistical dialog systems, as well as natural language understanding and adaptive multimodal interfaces.
Quick Links
-
Researchers
-
Awards
-
AWARD Mitsubishi Electric Group Wins Minister of Internal Affairs and Communications Award at CEATEC 2026 for TUSS Technology Date: October 13, 2026
Awarded to: Mitsubishi Electric Group, including Mitsubishi Electric Research Laboratories (MERL)
MERL Contacts: Christoph Boeddeker; Jonathan Le Roux; Yoshiki Masuyama; Julius Richter; Gordon Wichern
Research Areas: Artificial Intelligence, Machine Learning, Speech & AudioBrief- Mitsubishi Electric Group received the Minister of Internal Affairs and Communications Award at CEATEC 2026 for its Task-Aware Unified Source Separation (TUSS) technology. Originally developed at Mitsubishi Electric Research Laboratories (MERL) and first introduced in a paper published on arXiv in October 2024 and subsequently presented at ICASSP 2025, TUSS was further advanced in collaboration with Mitsubishi Electric for real-world applications. Following a press release in August 2026, the technology was demonstrated at CEATEC 2026, held at Makuhari Messe, Japan, from October 13–16, 2026.
TUSS is a unified, prompt-driven sound separation technology that enables a single AI model to perform a wide range of sound separation and extraction tasks. By specifying the desired sound sources through prompts, the system can separate speech, singing voices, musical instruments, machinery sounds, and other acoustic events from complex mixtures, without requiring a separate model for each task. This flexibility enables applications ranging from speech enhancement and recognition to music production, machine monitoring, and acoustic scene understanding.
At CEATEC, TUSS was presented as the "ears of physical AI," demonstrating how sound separation can help robots and other intelligent systems perceive their environments beyond visual information. Potential applications include disaster response, where rescuers could identify voices calling for help amid background noise, and industrial environments, where separating machinery sounds can support anomaly detection and situational awareness. The technology was recognized for its versatility, efficiency, and potential to improve the reliability of physical AI systems operating in complex real-world environments.
The demonstration and award attracted extensive media attention in Japan, including coverage by major television networks such as NHK, TBS, TV Tokyo, TV Asahi, Fuji TV, and Nippon TV, as well as numerous newspapers and technology publications. The technology was also featured internationally on NHK World.
For more information, see the official CEATEC award announcement and a presentation of TUSS at CEATEC 2026.
- Mitsubishi Electric Group received the Minister of Internal Affairs and Communications Award at CEATEC 2026 for its Task-Aware Unified Source Separation (TUSS) technology. Originally developed at Mitsubishi Electric Research Laboratories (MERL) and first introduced in a paper published on arXiv in October 2024 and subsequently presented at ICASSP 2025, TUSS was further advanced in collaboration with Mitsubishi Electric for real-world applications. Following a press release in August 2026, the technology was demonstrated at CEATEC 2026, held at Makuhari Messe, Japan, from October 13–16, 2026.
-
AWARD MERL Team Wins Real-TSE Challenge Track 2 on Offline Target Speaker Extraction Date: July 6, 2026
Awarded to: Dominik Klement, Yoshiki Masuyama, Christoph Boeddeker, Kohei Saijo, Julius Richter, Gordon Wichern, and Jonathan Le Roux
MERL Contacts: Christoph Boeddeker; Jonathan Le Roux; Yoshiki Masuyama; Julius Richter; Gordon Wichern
Research Areas: Artificial Intelligence, Machine Learning, Speech & AudioBriefMERL's Speech & Audio team, led by MERL intern Dominik Klement, ranked 1st out of 11 teams in Track 2, "Offline Target Speaker Extraction," of the Real-TSE Challenge. The challenge focuses on target speaker extraction (TSE) from real-world conversational recordings in either English or Chinese, where the goal is to extract the speech of a target speaker in the presence of interfering speakers, background noise, and reverberation.
While modern TSE systems have achieved strong performance on simulated speech mixtures, their performance can degrade considerably on real-world recordings due to the mismatch between simulated training data and actual conversational environments. The Real-TSE Challenge was designed to advance TSE under these realistic conditions, using real far-field conversational recordings for evaluation.
The MERL team won Track 2 by focusing on training data and curriculum learning rather than introducing a new model architecture. Starting from a strong speech separation model, the team progressively trained the system on fully overlapping synthetic speech, simulated conversations, realistic far-field mixtures, and finally real conversational recordings. This approach reduced the token error rate (TER), measured at either the word (English) or character (Chinese) level, from 70% to 37% on the development set and achieved a final TER of 61.3% on the evaluation set, best among the 11 participating teams. The team also topped the leaderboard in terms of the aggregate ranking across the four measures evaluating intelligibility, target speaker presence rate, speaker similarity, and perceptual quality.
The team also investigated the reliability of the challenge metrics and demonstrated that neural network-based speaker similarity and predicted speech-quality scores could be substantially improved without a corresponding improvement in perceptual quality. Because learned metrics can be susceptible to adversarial attacks or optimization that exploits weaknesses in the metric itself, these findings highlight both the importance of realistic training data for real-world TSE and the need for robust evaluation metrics when developing speech extraction systems.
A paper summarizing the team's findings will be presented at the IEEE Spoken Language Technology (SLT) 2026 workshop, to be held in Palermo, Italy from December 13-16, 2026.
REAL-TSE Challenge: Track 2 rankings — Offline Target Speaker Extraction Rank Team TER ↓ F1 ↑ SIM ↑ P808 ↑ Score ↓ 1 MERL 0.613 (1) 0.861 (2) 0.538 (3) 3.371 (2) 2.00 2 YiJiaHe 0.639 (2) 0.871 (1) 0.565 (1) 3.128 (9) 3.25 3 CARTSE 0.651 (3) 0.857 (4) 0.544 (2) 3.138 (8) 4.25 4 WasedaM 0.675 (5) 0.858 (3) 0.480 (6) 3.232 (6) 5.00 5 SonicAGI 0.680 (6) 0.851 (6) 0.471 (7) 3.258 (5) 6.00 6 WAKA 0.670 (4) 0.847 (8) 0.471 (7) 3.150 (7) 6.50 6 SHNU-TSE 0.731 (9) 0.840 (9) 0.507 (5) 3.362 (3) 6.50 7 ChuEst 0.710 (7) 0.831 (11) 0.532 (4) 3.064 (10) 8.00 8 pyannoteAI 0.728 (8) 0.855 (5) 0.464 (9) 2.904 (12) 8.50 9 AGH-JHU 0.743 (10) 0.837 (10) 0.434 (11) 3.335 (4) 8.75 10 WHU_IASP 0.757 (11) 0.850 (7) 0.465 (8) 2.961 (11) 9.25 11 CUDA_OUT_OF_MEMORY 0.827 (12) 0.819 (13) 0.364 (13) 3.435 (1) 9.75 12 BSRNN_EMB Baseline 0.829 (13) 0.829 (12) 0.417 (12) 2.875 (13) 12.50 12 BSRNN_TFMAP Baseline 0.838 (14) 0.829 (12) 0.443 (10) 2.756 (14) 12.50 ↓ Lower is better; ↑ higher is better. Parentheses show metric ranks. The score is the average of the four dense metric ranks; tied scores share a position. Best metric values are bold. P808 denotes DNSMOS-P808.
Source: Official REAL-TSE Challenge rankings. BSRNN entries are organizer baselines.
-
AWARD MERL Team Wins DCASE 2026 Challenge on Anomalous Sound Detection for Machine Condition Monitoring Date: June 30, 2026
Awarded to: Takuya Fujimura, Gordon Wichern, Yoshiki Masuyama, Christoph Boeddeker, Kohei Saijo, Julius Richter, Takahiro Edo, and Jonathan Le Roux
MERL Contacts: Christoph Boeddeker; Jonathan Le Roux; Yoshiki Masuyama; Julius Richter; Gordon Wichern
Research Areas: Artificial Intelligence, Machine Learning, Signal Processing, Speech & AudioBrief- MERL's Speech & Audio team ranked 1st out of 51 teams in the DCASE 2026 Challenge’s Task 2, “Noise-aware Unsupervised Anomalous Sound Detection for Machine Condition Monitoring.” The team was led by MERL intern Takuya Fujimura, and also included Gordon Wichern, Yoshiki Masuyama, Christoph Boeddeker, Kohei Saijo, Julius Richter, Takahiro Edo, and Jonathan Le Roux.
The IEEE AASP Challenge on Detection and Classification of Acoustic Scenes and Events (DCASE Challenge), started in 2013, has been organized yearly since 2016, and gathers challenges on multiple tasks related to the detection, analysis, and generation of sound events. This year, the DCASE 2026 Challenge received 421 submissions from 135 teams across seven tasks.
The MERL team won Task 2, Noise-aware Unsupervised Anomalous Sound Detection for Machine Condition Monitoring, which aims at building noise-robust systems for automatically detecting machine failure via microphones when only normal machine operating data is available for system development. Task 2 was by far the most popular out of the 7 DCASE 2026 tasks, with 51 teams submitting 168 entries. The MERL team's system was built around MERL’s recently proposed paradigm of noise-aware self-supervised learning, which extracts noise robust features leveraging two-channel recordings, in which one microphone is used to capture noise. Anomaly detection is then performed in the extracted denoised feature space using advanced score normalization. The team's best submission obtained a composite score of 70.24% on five evaluation machines, largely outperforming the 2nd best team's 65.45%.
MERL also participated in Task 4, Spatial Semantic Segmentation of Sound Scenes (S5) and placed 3rd out of 10 teams in separation performance. Our cascaded system consists of universal sound separation with source counting, source classification, and class-aware refinement, where the separation and refinement modules are built upon MERL's TF-Locoformer separation technology. Notably, the team's best submission obtained a label prediction accuracy of 76.92% on the evaluation set, largely outperforming the 2nd best team's 65.54%.
- MERL's Speech & Audio team ranked 1st out of 51 teams in the DCASE 2026 Challenge’s Task 2, “Noise-aware Unsupervised Anomalous Sound Detection for Machine Condition Monitoring.” The team was led by MERL intern Takuya Fujimura, and also included Gordon Wichern, Yoshiki Masuyama, Christoph Boeddeker, Kohei Saijo, Julius Richter, Takahiro Edo, and Jonathan Le Roux.
See All Awards for Speech & Audio -
-
News & Events
-
NEWS MERL Congratulates Recipients of 2027 IEEE Technical Field Awards in Signal Processing Date: October 22, 2026
Where: Piscataway, NJ
MERL Contacts: Petros T. Boufounos; Jonathan Le Roux; Anthony Vetro
Research Areas: Artificial Intelligence, Computational Sensing, Machine Learning, Signal Processing, Speech & AudioBrief- IEEE has announced the recipients of two prestigious 2027 IEEE Technical Field Awards sponsored by Mitsubishi Electric Research Laboratories (MERL).
The 2027 IEEE James L. Flanagan Speech and Audio Processing Award will be presented to Chin-Hui Lee, Professor in the School of Electrical and Computer Engineering at the Georgia Institute of Technology. Lee is recognized for "contributions to and leadership in technologies that enable automatic speech and speaker recognition, including innovations in adaptive learning and discriminative training."
The 2027 IEEE Fourier Award for Signal Processing will be presented to Nicholas Dimitrios Sidiropoulos, Louis T. Rader Professor of Electrical and Computer Engineering at the University of Virginia. Sidiropoulos is recognized for "contributions to signal processing methods for analyzing complex data and identifying patterns in multiple dimensions."
The IEEE James L. Flanagan Speech and Audio Processing Award was established in 2002 to recognize outstanding contributions to the advancement of speech and/or audio signal processing. The IEEE Fourier Award for Signal Processing was established in 2012 to recognize outstanding contributions to signal processing outside the areas of speech and audio.
MERL is proud to sponsor these awards, recognizing outstanding researchers whose contributions advance the field of signal processing and its applications. MERL congratulates the 2027 recipients on their achievements.”
- IEEE has announced the recipients of two prestigious 2027 IEEE Technical Field Awards sponsored by Mitsubishi Electric Research Laboratories (MERL).
-
EVENT MERL Contributes to ICASSP 2026 Date: Monday, May 4, 2026 - , May 8, 2026
Location: Barcelona, Spain
MERL Contacts: Wael H. Ali; Petros T. Boufounos; Chiori Hori; Jonathan Le Roux; Yanting Ma; Hassan Mansour; Yoshiki Masuyama; Joshua Rapp; Anthony Vetro; Pu (Perry) Wang; Gordon Wichern
Research Areas: Artificial Intelligence, Computational Sensing, Computer Vision, Machine Learning, Optimization, Signal Processing, Speech & AudioBrief- MERL has made numerous contributions to both the organization and technical program of ICASSP 2026, which is being held in Barcelona, Spain from May 4-8, 2026.
Sponsorship
MERL is proud to be a Silver Patron of the conference and will participate in the student job fair on Thursday, May 7. Please join this session to learn more about employment opportunities at MERL, including openings for research scientists, post-docs, and interns. MERL Distinguished Research Scientists Petros T. Boufounos and Jonathan Le Roux will also present a spotlight session on MERL’s research in signal processing on Tuesday, May 5 at 13:05. Finally, MERL will sponsor a photo booth on Thursday, May 7 and Friday, May 8, where ICASSP participants can take professional photos with friends and colleagues, which will be emailed to them.
MERL is also pleased to be the sponsor of two IEEE Awards that will be presented at the conference. We congratulate Prof. Nasir Ahmed, the recipient of the 2026 IEEE Fourier Award for Signal Processing, and Dr. Alex Acero, the recipient of the 2026 IEEE James L. Flanagan Speech and Audio Processing Award.
Technical Program
MERL is presenting 8 papers in the main conference on a wide range of topics including source separation, spatial audio, neural audio codecs, radar-based pose estimation, camera-based airflow sensing, radar array processing, and optimization. Another paper on neural speech codecs will be presented at the Low-Resource Audio Codec (LRAC) Satellite Workshop. MERL researchers will also present two articles published in IEEE Open Journal of Signal Processing (OJSP) on music source separation and head-related transfer function (HRTF) modeling. Finally, Speech and Audio Team members Yoshiki Masuyama and Jonathan Le Roux co-organized a Special Session on Neural Spatial Audio Processing, which will feature six oral presentations.
About ICASSP
ICASSP is the flagship conference of the IEEE Signal Processing Society, and the world's largest and most comprehensive technical conference focused on the research advances and latest technological development in signal and information processing. The event attracts more than 4000 participants each year.
- MERL has made numerous contributions to both the organization and technical program of ICASSP 2026, which is being held in Barcelona, Spain from May 4-8, 2026.
See All News & Events for Speech & Audio -
-
Research Highlights
-
Internships
-
SA0342: Internship - Sound event and anomaly detection
-
SA0341: Internship - Acoustic metamaterials and active noise control
-
CV0355: Internship - 3D Reconstruction of Dynamic Scenes
See All Internships for Speech & Audio -
-
Openings
-
SA0297: Postdoctoral Research Fellow - AI for Science
-
CI0177: Postdoctoral Research Fellow - Agentic AI
See All Openings at MERL -
-
Recent Publications
- , "FurnitureVLA: Learning Long-Horizon Bimanual Furniture Assembly with Vision-Language-Action Model", Conference on Robot Learning (CoRL) Workshop on The Action Gap: Large Generative Models Learn Rich Knowledge, November 2026.BibTeX TR2026-174 PDF
- @inproceedings{Ma2026nov,
- author = {Ma, Chenyang and Yang, Yue and Corcodel, Radu and Jain, Siddarth and Wu, Andrew and Hori, Chiori and Romeres, Diego},
- title = {{FurnitureVLA: Learning Long-Horizon Bimanual Furniture Assembly with Vision-Language-Action Model}},
- booktitle = {Conference on Robot Learning (CoRL) Workshop on The Action Gap: Large Generative Models Learn Rich Knowledge},
- year = 2026,
- month = nov,
- url = {https://www.merl.com/publications/TR2026-174}
- }
- , "When Speech is Noise: Speech Removal for Machine Anomaly Detection", Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE), October 2026.BibTeX TR2026-162 PDF
- @inproceedings{Edo2026oct,
- author = {Edo, Takahiro and Wichern, Gordon and Fujimura, Takuya and Boeddeker, Christoph and Masuyama, Yoshiki and Richter, Julius and Saijo, Kohei and {Le Roux}, Jonathan},
- title = {{When Speech is Noise: Speech Removal for Machine Anomaly Detection}},
- booktitle = {Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE)},
- year = 2026,
- month = oct,
- url = {https://www.merl.com/publications/TR2026-162}
- }
- , "Anomalous Sound Detection Meets Noise-Aware Self-Supervised Learning", Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE), October 2026.BibTeX TR2026-165 PDF
- @inproceedings{Fujimura2026oct,
- author = {Fujimura, Takuya and Wichern, Gordon and Masuyama, Yoshiki and Boeddeker, Christoph and Saijo, Kohei and Richter, Julius and Edo, Takahiro and {Le Roux}, Jonathan},
- title = {{Anomalous Sound Detection Meets Noise-Aware Self-Supervised Learning}},
- booktitle = {Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE)},
- year = 2026,
- month = oct,
- url = {https://www.merl.com/publications/TR2026-165}
- }
- , "Explainable Unsupervised Sound Anomaly Detection via Sparse Feature Decomposition", Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE), October 2026.BibTeX TR2026-166 PDF
- @inproceedings{Paissan2026oct,
- author = {Paissan, Francesco and Wichern, Gordon and Masuyama, Yoshiki and {Le Roux}, Jonathan},
- title = {{Explainable Unsupervised Sound Anomaly Detection via Sparse Feature Decomposition}},
- booktitle = {Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE)},
- year = 2026,
- month = oct,
- url = {https://www.merl.com/publications/TR2026-166}
- }
- , "An S5 System based on Multi-stage Separation and Classification", Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE), October 2026.BibTeX TR2026-163 PDF
- @inproceedings{Saijo2026oct,
- author = {Saijo, Kohei and Masuyama, Yoshiki and Boeddeker, Christoph and Wichern, Gordon and Richter, Julius and Edo, Takahiro and {Le Roux}, Jonathan},
- title = {{An S5 System based on Multi-stage Separation and Classification}},
- booktitle = {Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE)},
- year = 2026,
- month = oct,
- url = {https://www.merl.com/publications/TR2026-163}
- }
- , "Evaluating Inference-time Algorithms for Semantic Sound Scene Segmentation", Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE), October 2026.BibTeX TR2026-164 PDF
- @inproceedings{Sridhar2026oct2,
- author = {Sridhar, Sripathi and Wichern, Gordon and Masuyama, Yoshiki and Cartwright, Mark and {Le Roux}, Jonathan},
- title = {{Evaluating Inference-time Algorithms for Semantic Sound Scene Segmentation}},
- booktitle = {Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE)},
- year = 2026,
- month = oct,
- url = {https://www.merl.com/publications/TR2026-164}
- }
- , "Echoes after Edits: Room Impulse Response Estimation for Geometry Update", Interspeech, DOI: 10.21437/Interspeech.2026-2514, September 2026, pp. 2958-2962.BibTeX TR2026-140 PDF
- @inproceedings{Bhosale2026sep2,
- author = {Bhosale, Swapnil and Masuyama, Yoshiki and Chatterjee, Moitreya and Boeddeker, Christoph and Richter, Julius and Wichern, Gordon and {Le Roux}, Jonathan},
- title = {{Echoes after Edits: Room Impulse Response Estimation for Geometry Update}},
- booktitle = {Interspeech},
- year = 2026,
- pages = {2958--2962},
- month = sep,
- doi = {10.21437/Interspeech.2026-2514},
- issn = {2958-1796},
- url = {https://www.merl.com/publications/TR2026-140}
- }
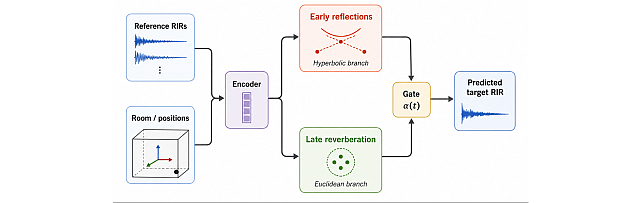
- , "Dual-Geometry Manifolds for Few-shot RIR Prediction", Interspeech, September 2026, pp. 2963-2967.BibTeX TR2026-139 PDF Software
- @inproceedings{Bhosale2026sep,
- author = {Bhosale, Swapnil and Wichern, Gordon and Masuyama, Yoshiki and Chatterjee, Moitreya and Boeddeker, Christoph and Richter, Julius and Zhu, Xiatian and {Le Roux}, Jonathan},
- title = {{Dual-Geometry Manifolds for Few-shot RIR Prediction}},
- booktitle = {Interspeech},
- year = 2026,
- pages = {2963--2967},
- month = sep,
- issn = {2958-1796},
- url = {https://www.merl.com/publications/TR2026-139}
- }
- , "FurnitureVLA: Learning Long-Horizon Bimanual Furniture Assembly with Vision-Language-Action Model", Conference on Robot Learning (CoRL) Workshop on The Action Gap: Large Generative Models Learn Rich Knowledge, November 2026.
-
Videos
-
Software & Data Downloads
-
Dual-Geometry Manifolds for Few-shot RIR Prediction -
Sim-to-Real Neural Field -
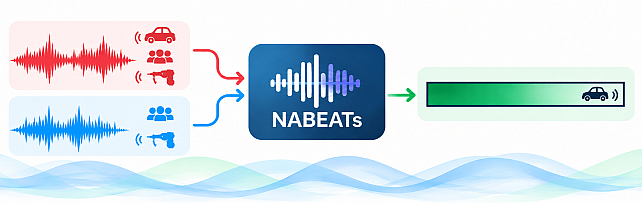
Noise-Aware Audio Representation Learning -
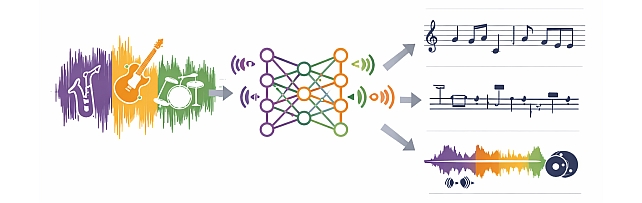
Embracing Cacophony -
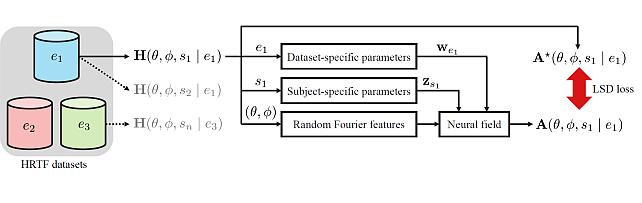
Subject- and Dataset-Aware Neural Field for HRTF Modeling -
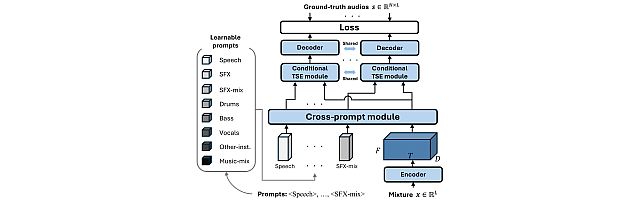
Task-Aware Unified Source Separation -
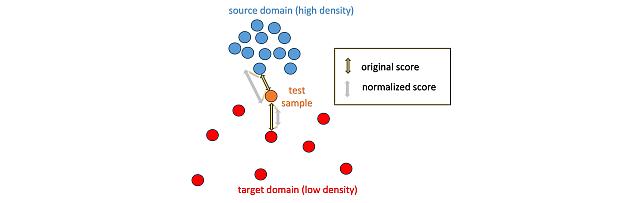
Local Density-Based Anomaly Score Normalization for Domain Generalization -
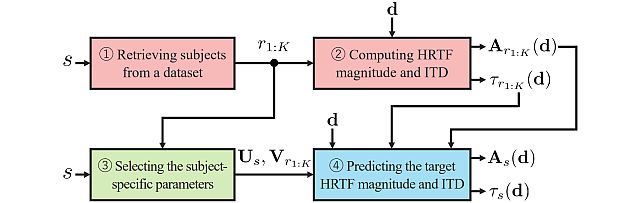
Retrieval-Augmented Neural Field for HRTF Upsampling and Personalization -
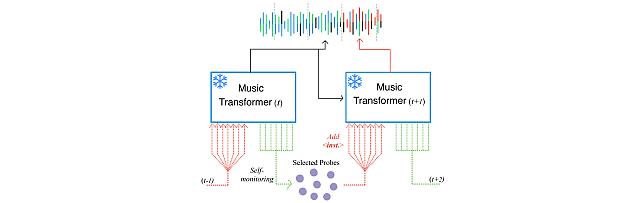
Self-Monitored Inference-Time INtervention for Generative Music Transformers -
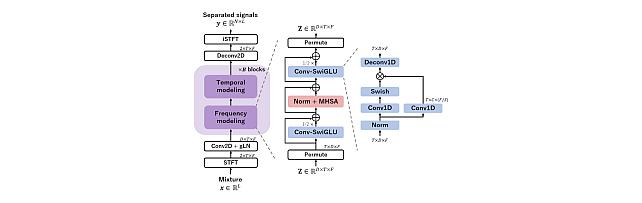
Transformer-based model with LOcal-modeling by COnvolution -
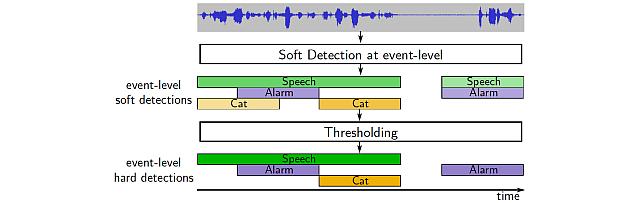
Sound Event Bounding Boxes -
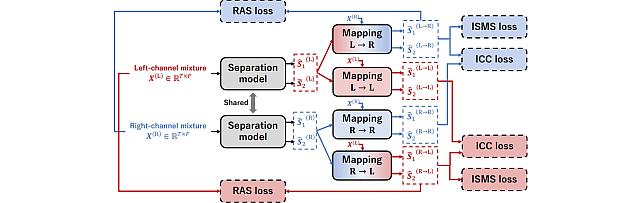
Enhanced Reverberation as Supervision -
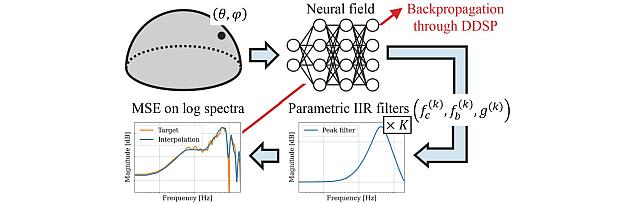
Neural IIR Filter Field for HRTF Upsampling and Personalization -
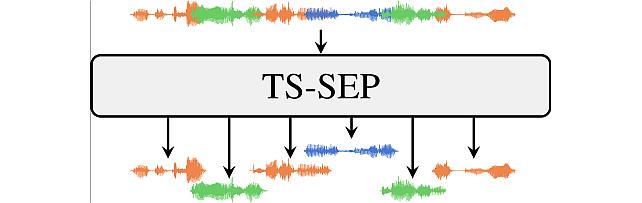
Target-Speaker SEParation -
Hyperbolic Audio Source Separation -
Audio-Visual-Language Embodied Navigation in 3D Environments -
Audio Visual Scene-Graph Segmentor -
Hierarchical Musical Instrument Separation -
Non-negative Dynamical System model -
Stochastic Interpolants for Speech Enhancement and Separation
-